Some Bits: Nelson's weblog

New weblog software: Flourish

Hello friends, big day on my little blog! If you’re reading this post you’re reading my blog via a brand new blog engine. I call it “Flourish.” If all goes well you won’t really notice a change. I tried to get the Atom feed right so posts don’t show up as new, but if they do be assured it’s a one-time thing.

Much love to Rael Dornfest and his Blosxom blog engine. I’ve been running that for 25 years. I may be the last person left who was running it, or at least the 2004 Perl CGI. Flourish is a static generator I custom built in Python with Claude Code / Opus. I’d spent several weeks hand-writing a prototype a couple of years ago and couldn’t ever get it launch-ready. The AI rewrote and finished it in two days with a much better testing plan than I ever would have done.

The new blog looks more or less the same as the old blog. A few broken things fixed and some cosmetics improved. There’s a slick JavaScript page search now, try it! Once the new system proves itself I plan to modernize the visual design. Who knows, I may even start blogging more!

I cannot say enough about how great AI coding tools have been for me. In just a few weeks I’ve totally updated the server software infrastructure, launched a major new personal content site, built a new blog engine, and done a bunch of little projects. I know there’s a lot of tension about AI coding but I’ve found it very productive for my personal hobby projects. And fun too, I feel like my expertise still matters. I’m just not bogged down anymore in the scut work.

New server for somebits.com

Somebits.com has a new server. It’s been up for a few days and seems to be working great. Big things hosted here:

The new server is hosted at OVHCloud and runs on NixOS. For 20+ years I’ve been hand-managing servers like this. This time around I got an AI to build it for me. It was a very good experience and I’m quite satisfied with the result. Nix feels like a good match for AIs: the entire operating system is described declaratively so there’s no managing of running ssh commands and tracking their side effects.

The Year of Linux on My Desktop

For the first time in about 25 years I’m running a Linux desktop. It’s great!

I used to use Linux all the time. But even back in the early ’00s all I was running for work was ssh terminals and a web browser and Windows did that just fine. And for gaming you had to have Windows. I had a few years of using a Mac, then switched back to Windows once WSL got good enough to have a local Unix.

But I liked to try Linux out every couple of years. Last month I installed Bazzite on an external drive to test it out. I liked it so much I’m now converting entirely. I even bought a new computer and monitor for it.

A key factor in switching is that Bazzite is a particularly well-engineered consumer product. It installs simply with a bunch of codecs and drivers so that my fancy HDR monitor simply worked. Bazzite is a gaming-oriented OS and it only exists because Valve put a lot of effort into making Linux gaming work with the Proton compatibility layer. These days Linux plays most games better than Windows itself does and thanks to the success of the SteamDeck, a lot of devs are testing on Linux.

KDE Plasma is another key part of my good experience. It took 27 years but Linux finally has a pretty usable desktop environment out of the box. Multiple monitors work, display scaling works, HDR even works! There’s still some rough edges but all in all it’s pretty good. A lot of things work better than they do on Windows.

I’ve been having a lot of fun tinkering with stuff. Quieting fan noise, getting wake-on-LAN working, streaming Plexamp to my Sonos... Some of these things are probably doable in Windows too but it’s sure a pleasure figuring it out in Linux. Having AIs to ask questions of is a big help too, I wouldn’t have found this so easy two years ago.

Bazzite was a great first date but I’ve since switched to Nobara Linux. They’re very similar, both Fedora variants. Bazzite is an immutable OS which is great for an appliance like a TV PC but not so good for tinkering. Nobara is a more traditional “install what you want” setup. I could also just use Fedora directly but the extra customizations and drivers add enough value add I am glad to have it.

AI enhanced search

LLMs are good search helpers. Here’s three search tools I use every day. All of these use an AI to synthesize answers but also provide an essential feature: specific web search results for you to verify and further research. I use these for conversational inquiries in addition to more traditional keyword searches.

Phind is an excellent free LLM + search engine. The AI writes an answer to your query but is very careful to provide footnotes to a web-search-like list of links on the right. I use this mostly for directed search queries, things like “what’s an inexpensive TV streaming device?” where I might have used keyword search too. The Llama-70b LLM that powers the free version is quite good, sometimes I have general conversations with it or ask it to generate code.

Bing CoPilot has a very similar output result to Phind. I find it a little less useful and the search result links are less prominent. But it’s a good second opinion. Bing has been a very good search engine for 10+ years, I’m grateful to Microsoft for continuing to invest in it. CoPilot results are sometimes volunteered on the main Bing page but you often have to click to get to the ChatGPT 4 Turbo enhanced pages.

Kagi is what I use as my general search engine, my Google replacement. It mostly gives traditional keyword search results but sometimes it will volunteer a “Quick Answer” where Claude 3 Haiku synthesizes an answer with references. You can also request one. I think Phind and CoPilot do a better job but I appreciate when Kagi intercepts a keyword search I did and just gives me the right answer.

Google has tried various versions of LLM-enhancement in search, I think the current version is called AI Overviews. It’s not bad but it’s also not as good as the others.

Not mentioned here: ChatGPT or Claude. Those are general purpose LLMs but they don’t really give search results or specific references. In the old days they’d make up URLs if you asked but that’s improving.

8BitDo Game Controllers

8BitDo makes good game controllers. A wide variety of styles from retro to mainstream, with some unusual shapes. And wide compatibility with various systems: PC, Macs, Switch, Android. They’re well built, work right, and quite inexpensive. A far cry from the MadCatz-style junk we used to get.

The new hotness is the Ultimate 2C, an Xbox-style wireless controller for the very low price of $30. But it works great, doesn’t feel cheap at all. The fancier mainstream choice is the Ultimate 2.4g at $50 which includes a charging stand and extra reprogrammability.

But what’s really interesting to me are the odd layouts, often small or retro. The SN30 Pro is particularly interesting as a portable controller. SNES-styling but a full XBox style modern controller with two analog sticks, easy to throw in a suitcase.

There’s a lot of fiddly details for this class of device. Controller type (XInput, DInput, switch, etc), wireless interface (Bluetooth or proprietary), etc. 8BitDo makes good choices and implementations for all that stuff I’ve tested. They seem to work well with Steam. They’re a popular brand so well tested. It helps that PC game controllers have mostly standardized around the Xbox layout and XInput. Steam can patch over any rough spots for older games.

PreSonus Eris speakers

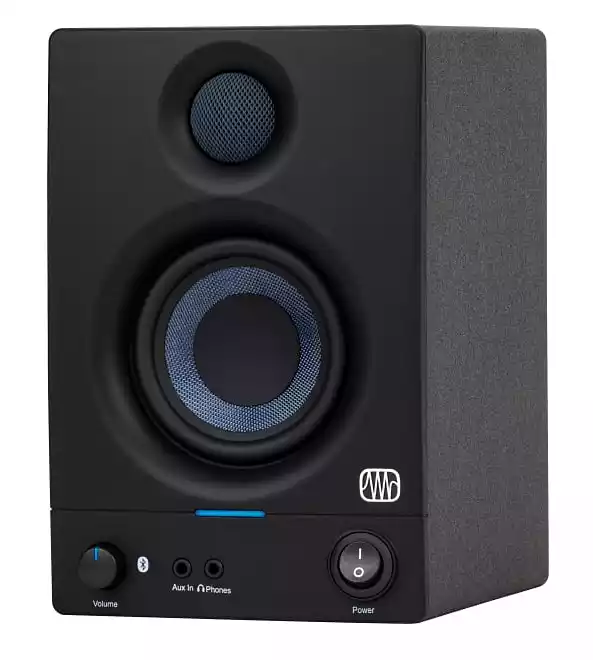
PreSonus makes good computer speakers. They’re marketed as “reference monitors” but at $100 for a small set I have my doubts about their referenceness. Fortunately I have a tin ear and they sound just fine for my computer playing YouTube videos, compressed music, games. Wirecutter agrees.

The specific ones I have are these 3.5" Bluetooth speakers for $150. Inputs are RCA line-in, balanced, and Bluetooth, also an Aux-In and Headphone jacks on the front. Decent amplifier, plenty loud for an office. There’s 100Hz and 10kHz equalization knobs and a Bluetooth pairing button in the back. The “Gen 2” version includes an optional standby mode for power savings which seems to work fine. The cabinet is MDF and while it’s light it doesn’t have that hollow sound of cheap plastic. The website only promises 80 Hz so these are not the speakers for bass thumping.

Fifteen years ago I recommended the M-Audio speakers. IIRC their quality went downhill, maybe they went to plastic enclosures? I also had some Creative Mackie speakers but they have a manufacturing problem that causes them to fail after a few years. We’ll see how long these PreSonus ones last.

I’m self-conscious how this post looks like a spammy marketing affiliate page written by an AI. It’s not! I just like the product.

Phanpy, a Mastodon client

Phanpy is good software for reading Mastodon or other Fediverse posts. Astonishingly it’s an open source passion project from a single developer, Chee Aun. Its quality is extraordinary, better than most commercial social media software.

There’s so many good things about Phanpy that it’s hard to know where to start. It has several innovations for reading social media. My favorite is the Boost Carousel, a way to collapse the ordinary spammy boosts / retweets so they don’t overwhelm original posts. There’s also the catch-up UI, a novel approach to the problem of helping you read the last 12+ hours of posts quickly.

Mostly I like Phanpy because it’s just very high quality. All the little things work so well, like the post UI and the image display and the notifications. The account switcher is great too. So many software products are full of rough edges and bugs and annoyances. Phanpy is immaculate.

It’s easy to get started. Phanpy runs as a PWA so there’s not even really an install, you just visit the website, approve the login from your main Mastodon host, and you’re up and running. I use it that way in my browser on desktop but have it installed as a formal PWA on my phone. Works great, including notifications.

Honestly surprised a product of this quality is an open source project. AFAICT Chee Aun has worked full time on it for at least a year and he is very good at what he does. He has a modest request for sponsors but I hope somehow his work ends up paying him very well or compensates him in some other way.

Kagi is a good search engine

Google search is overwhelmed with spam these days. Back in January I switched to Kagi and have been happy with it. It’s not free but there’s a limited trial to check it out. I pay $10/mo for unlimited access. Turns out I do about 50 searches a day.

I’m unclear on how Kagi works or why it’s better than Google. It seems to be returning more quality results and less SEO-churn old-but-look-new pages. I see some AI-padded content on the results at times but mostly better stuff. I assume under the hood it’s mostly Bing. Whatever they’re doing works for me, a bit of a surprise since the similar DuckDuckGo has never succeeded for me.

Kagi is ad-free. It has some interesting advanced features but I don’t use them often. Honestly most of my queries are navigational. Kagi does have a new sidebar LLM feature where it generates a synthetic answer with references, much like Bing, sometimes I find that useful.

My biggest annoyance is Kagi’s local and maps search is nowhere near as good as Google. It’s Apple Maps; their cartography is good these days but they don’t have the local search data with user reviews. Also Kagi doesn’t work in incognito mode because I’m not logged in. They have a workaround for it but then you lose anonymity.

I have a feeling I’m going to be changing search engines several times in the next few years. It’s a shame Neeva didn’t make it, I feel like now is the best time ever for serious search competition. I’m grateful Bing is still viable. And maybe Google will finally get its act together.

Restic

Restic is good backup software. It’s a command line tool for backing up filesystems to various local and remote options. It is well documented, easy to set up, secure, and quite fast. It’s a very professional product. I am now backing up all my Linux systems with it. Note it’s a sysadmin tool; I don’t think there’s a friendly consumer GUI.

The underlying data model is its genius. Backups are stored in a repository, some complex hash-index blob store that I don’t understand at all. But it seems able to quickly store blocks of data and de-duplicate them so incremental backups are efficient. It’s encrypted and the blobs in the repository are stored in a simple filesystem. That makes it easy and safe to backup to all sorts of places including untrusted remote stores. I’m doing remote backups to BackBlaze’s S3-like filesystem for about $1/month.

The repo format means you need a working copy of restic to restore your files. I’m OK with that, it’s open source. And the tool is great. It has options for bulk restore, individual file restore, interactive restore via a FUSE filesystem. Also a check command you can use to verify subsets of the backup on your own schedule.

The basic command line tool is good but limited. I’m using resticprofile as a frontend. You set up a single config file and it takes care of running restic for you, even scheduling itself in cron. It’s a bit idiosyncratic but seems to work fine once set up. backrest is another frontend, I haven’t tried it.

Shout out to rsnapshot, I’ve been backing up with it for 18 years now. Time for something new. rsnapshot is pretty slow on lots of little files and remote backups were awkward. Years ago I said 5 minutes to do an incremental backup of 165GB was good; that takes more like 5 seconds in Restic now.

Proxmox

Proxmox is good software for a home datacenter. It’s an OS you install on server hardware that lets you easily run multiple virtual machines and LXC containers. It also manages disk storage and has some more complex support for high availability in a cluster, distributed storage via Ceph, etc. But even with a single small server running a single VM Proxmox offers advantages.

my home server

I’ve had a Linux server in my home for 20+ years now. Every few years I have to rebuild it, often from the ashes of failed hardware, and it’s always a tedious manual process. Now my server is truly virtualized, a nice tidy KVM/QEMU virtual machine with a disk I can snapshot and back up. And migrate an exact copy to new hardware in minutes.

Right now I’m mostly running my stuff in one big VM under Proxmox that I migrated from the old server. But I’m slowly moving services to separate VMs and LXC containers. So now my SMB server for Sonos lives in one container, and my Plex server in another, and my Unifi router manager in a third. All running isolated from each other. This feels tidier, more manageable.

Proxmox does a lot of nice things for home-scale servers. It handles ZFS for filesystems, including snapshots and backups. It has a nice web GUI for managing things, even graphical consoles where needed. And I like how it supports both VMs and containers as a first class things. There’s other ways to manage guest systems, like Docker (containers only) or VMware ESXi (proprietary, VMs only). Proxmox feels the right scale for me. I’ve spent about a month tinkering with it and like the software quite a bit. It’s usable, well documented, and seems well designed.

Obsidian

Obsidian is good software for taking and organizing notes. There are many apps for this task, Obsidian is my current favorite. In the past I’ve used a text file, SimpleNote, Standard Notes, Joplin. I never used emacs org-mode nor Evernote. Obsidian works reliably and is simple yet powerful.

The core Obsidian data model is “a folder of markdown files”. That’s it, really basic, and the files are easily usable as ordinary files. There’s natural support for links between notes. There’s also a metadata option I don’t use. I appreciate it’s easy to move files in and out of Obsidian.

But where Obsidian really shines is the plugin ecosystem. I don’t actually use many plugins, just HTML export and system tray. But I appreciate the power. If you check the reddit you’ll find an enthusiast community that does a lot more complicated stuff, turning their Obsidian archives into 1000+ article infobases. Me, I just write grocery lists and blog posts.

Obsidian is not open source. They’re thoughtful about why not. (Logseq is a popular open source alternative). The core product is free and works great. I am paying $96 per year for syncing. It’s pricy but it works well and I want to support the company. You can do your own free sync but none work as easily.

I want to give a shout-out here to Simplenote, an excellent and venerable free product. And after a brief lull development started again in 2020. Kudos to Matt and Automattic for supporting that tool. I like Obsidian’s fanciness but Simplenote is pretty great.

Cronometer is a good food diary

Recently I switched to a new calorie counting app, Cronometer. I’m quite happy with it. It’s a huge improvement over MyFitnessPal (MFP) or Lose It and is not exploitative like Noom.

The key improvement with Cronometer is accuracy, particularly good data sources for nutrition information. MFP offered obviously wrong entries from random people, sapping my confidence. Also it’s quicker to log things from a trusted database.

And the app works well. Cronometer’s UI is modern and easy to use. It doesn’t display extra distractions. MFP’s insistence on scolding me about things I don’t care about was a bummer. The data sync is fast. And they have a good data export, something MFP won’t do.

I have some minor complaints. Cronometer is very excited to track macros and every single obscure nutrient (threonine, selenium?!). I really only want to track calories. Fortunately the other things don’t take up too much space. They also display ridiculous calorie precision in the diary. But that feels like a rare UI mistake, not a general design ethos.

The free version is pretty complete. The $55/year paid plan adds a bunch of stuff, the one I care about is dividing your diary up into individual meals.

I have a long history with food diaries, more off than on. Having a good app that I trust and is easy to use is important.

What are passkeys?

That’s the post. What are passkeys? I don’t have answers, just questions. I believe passkeys are a great idea but the tech world is doing a terrible job explaining them. Someone really needs to explain how passkeys work in Internet products. Existing descriptions aren’t sinking in, as evidenced by the confusion online. For instance this Hacker News discussion where a new Passkey product announcement is met with a bunch of basic questions about what Passkeys even are.

Update: see these newer Passkey overview articles here and here. Also my own notes written after this was published.

The tech is pretty well defined: Passkeys are a password replacement that uses WebAuthn to log you in to stuff. Companies are widely deploying them now: Apple, Google, Microsoft, 1Password. Passkeys are an industry consensus and are arriving in production very soon or already has. Great! Now then what are they really?

Here’s some questions from my perspective as an ordinary if expert Internet user. I own a few computers and phones and don’t want to trust just one company with my entire digital identity.

  • What device holds my passkey(s)? Let’s assume it’s my phone.
  • What software do I use for my passkeys? I trust 1Password already; can they do all my Passkeys for me? Or can my web browser hold my passkeys?
  • Who issues me a passkey? Let’s say Google issues me one.
  • Logging in to Google with a Google passkey is easy, right? I just unlock my phone and press a button? Awesome!
  • Do I have many passkeys or just one?
  • How do I log in to some other website, say my Mastodon server? Can I use my Google passkey there too? Or does my Mastodon server issue a different passkey?
  • How do I log in to Google if I temporarily don’t have my phone with my passkey on it?
  • How do I reset a passkey if my phone is stolen?
  • How do I log in to other sites if Google goes offline or revokes my account or something?
  • How do I migrate my passkeys to a new phone?
  • Can I store the same passkey on several devices for convenience?
  • Can that passkey be automatically synced between devices, securely?
  • Can I use multiple passkeys to log in to the same account?
  • Can I share a passkey with my partner so we can both log in to the thermostat?
  • Can I still use passwords to log in to a site even with a passkey enabled?
  • I have two factor authentication with a TOTP code generator. Does the passkey replace my password? The code? Both?
  • I really want to use two factors for my bank: I don’t trust just my passkey on my phone to log in me in. How does that work?
  • Can I use passkeys to log in to apps and computers? Or just web sites?
  • If I own a fancy Yubikey device can I use it as a passkey? Use it to protect my passkey?
  • Is there a way for me to generate a passkey myself so I don’t have to trust a company to issue it for me?
  • Can I turn off passkey on a site and log in some other way?

The core of many of these questions is exactly what a passkey is. What I want to read is an article that explains the gestalt of passkeys and identity on the Internet in a way the answers to all these questions becomes clear.

My understanding from what I’ve read is that passkeys are an authentication token, basically a replacement for a single secret like a password. Naively that’d mean I’d need a different passkey for every website I log in to (just like I need different passwords). But I could be wrong. Or maybe the passkey intention is that we use federated logins, so sites like my Mastodon server use Google to help me log in with my Google passkey? (That’s an enormous business problem, if so.)

My other understanding is a lot of my questions don’t have good answers yet. Ie: revocation of a passkey or migrating to new devices. The product announcements from various companies say “trust us, that’s coming soon”. But I do not trust a company like Google or Apple to later add a feature that will make it easy for me to migrate away from their loving embrace. That stuff has to be defined and working before Passkeys are a good product for consumers and the Internet.

Update: Ensuing discussion has made one thing clear: you don’t share passkeys between sites. You have a separate passkey for each thing you log in to. That clears up several of my questions. I don’t know how I didn’t understand that already but the confusion isn’t mine alone.

There really needs to be a good, clear description of Passkey as a product so questions like this aren’t being asked over and over again. I’m hopeful the folks working on this stuff understand the answers and just haven’t communicated it well.

Passkey authenticators for consumers (May 2023)

After yesterday’s post about passkeys I got enough answers to learn how to use passkeys myself as a consumer. Here’s what I learned. If you want to try it yourself, passkeys.io is a nice demo server.

Passkeys work a lot like passwords do today. You create a different passkey for each website and use it to log in. Your passkeys are stored in what’s called a “Passkey Authenticator”, agent software on your computer. (Behind the scenes passkeys use public key systems that are better than passwords.) Your phone probably works today as a passkey authenticator but most sites don’t support passkeys yet.

Managing passkeys — backing up, migrating, sharing passkeys between devices — is still a work in progress. Android and Apple both support syncing passkeys between devices, that’s important so you can log in even if you don’t have your phone with you. Some software can also delegate. For instance Chrome on Windows will use Bluetooth to use a passkey on a nearby Android phone.

The passkey authenticator is the main user interface. The rest of this post is notes on what authenticators are available to consumers. See also this companion piece that’s a deep dive into the user experience on Android, Chromebooks, and Windows.

Apple seems the best implementation of a passkey authenticator today. It’s built in to Keychain, Apple’s existing authentication product that is pretty well designed. There’s a bunch of screenshots in this article of how the Apple experience works. My Apple-using friends say it’s pretty usable. Keychain syncs passkeys between devices via iCloud.

Android has a passkey authenticator built in called “Google Password Manager,” which already saves ordinary passwords you use in the phone’s web browser. Here’s Google’s docs for users about that and some technical notes on security. Android syncs syncs passkeys between devices. It’s also pretty usable but passkeys are Android-only, not available on desktop (yet).

Chrome on Windows or a Chromebook has passkey support. But the Chrome browser doesn’t store passkeys itself, it delegates to nearby Android devices via Bluetooth. Firefox and Edge on Windows can also do this delegation. Chrome can also delegate to Windows as the passkey authenticator instead of Android.

Microsoft Windows has an authenticator that is connected to Windows Hello, their relatively new login system. I don’t know much about it but it’s what you’d use to store passkeys on your Windows machine.

1Password, the password agent, is shipping passkey support in about a month. They have a demo that actually works on Chrome and Edge. It’s nice! In theory this should be a good cross-device way to manage and sync passkeys. I’m waiting for it before adopting passkeys widely.

Dashlane, the password agent, has passkey support. Sounds like early days but usable.

Yubikey, the hardware login token, has a passkey story. I don’t know much about it, their writing points out that passkeys aren’t really anything new and they’ve been doing this kind of thing all along.

Having spent most of a day playing with passkeys my impression is they work today and are usable. My main concern is there’s no support for migrating your passkeys out of, say, Google Password Manager and in to Apple Keychain. And I fear given business realities no one is in a hurry to enable that. The other problem is how long it will take sites to adopt passkeys; we’re going to be stuck with passwords for a good long time.
Noom is exploitative

I tried out Noom, the weight loss and cognitive behavioral therapy program. The app is more like CBT for upselling customers than CBT for weight loss. Now I’m hoping they’ll delete my sensitive medical data and refund the $3 they tricked me out of. (They did, quickly in response to my support email.)

I was excited to try Noom. I’ve used basic calorie counters in the past and was hoping for something better. I’m also curious about CBT. And a friend recommended it.

The account creation process goes OK at first. Then it gets more and more involved, taking 10–20 minutes to fill out the questions. There’s little UI tricks to keep you engaged: fake progress bars, questions injected at random intervals. Classic product UI hacking.

At first it told me that I’d reach my weight goal in about a year. Seemed reasonable! Then it kept shaving weeks off that as I answered questions, like I was making progress already. The conclusion it came to is that I was going to lose 18 pounds in the first month. Pretty sure that’s not possible, certainly not healthy.

Then the upselling begins. They ask some questions to find out your interests and then offer premium packages. “Folks who pay for this package lose 35% more weight” Look, I just want to try the basic thing.

It looks like a 7 day free trial but before you know it they want you to pay asserting “it costs $10 to offer a 7 day trial”. Really? They gave me a choice of what to pay from $0.50 to $18.83. I chose $3 and had to pay via PayPal / credit card; super sus they don’t just use Google Pay on the Android app.

They also try to get you to sign up your friends. They talk about how having folks involved in your program will make you more successful. Which is probably true but then immediately they’re asking for email addresses and offering discounts and gift certificates. It’s marketing, not therapy.

The whole thing was so sleazy and deceptive. Particularly for a therapy-like product. Real therapists have all sorts of ethical guidelines to stop them from exploiting their customers. Noom instead seems to be using CBT to trick customers into paying more. Gross, gross, gross.

Windy.com is good weather

I’ve found a mobile app for weather I finally like enough to be happy about paying for. Windy, best known for its website. The mobile app has extra phone features like notifications and home screen widgets. Also its UI is a little more understandable.

Windy makes a strong first impression with its colorful animation of winds. But wind speed is not that interesting to me. Windy also does an excellent job displaying radar, air quality, current thunderstorms, etc. Even weather station observations and webcams. All displayed beautifully and uniformly; that’s not easy!

But my favorite thing is the forecast view, hidden away in the website but a bit easier to find on mobile. It’s a lot of detail packed into a very small tabular display. I appreciate that it shows the full forecast by hour going out for days. Also the choice of forecast models; their website explains the options. It’s all very nerdy in the way I want. It’s not great at “weather at a glance” but is good for a deeper understanding.

Their business model seems to be a $19/mo yearly subscription. Their privacy policy is clear they won’t sell your data to third parties. The app says “we do not store your location on our servers”. Most weather apps are sleazy and sell your location to advertisers and data brokers.

Sadly they have nothing like Dark Sky’s unique microforecasts. Nothing to say “it will rain where you are standing in 7 minutes”. But they do have excellent presentation of large scale traditional forecasts.

Starlink in Nov 2022

My Starlink Internet service has gotten pretty bad; every evening I’m well under 50Mbps and some hours I only get 2Mbps. (Compare 100Mbps+ last year.) I’ve given up trying to stream 1080p video at night; that’s a pretty dismal result for a new Internet service in 2022.

Starlink imposed major restrictions on US customers last month: 1 TB / month data cap and expected download speeds dropped from 50-200Mbps to 20-100Mbps. Details of all that on my secret blog. Note they didn’t drop the price, we’re still paying $110/month.

Maybe the new caps will help the congestion? I’m sympathetic to their technical problem. They have limited bandwidth and they have to share it somehow. Caps are an awkward solution; most users have no idea how much bandwidth they are using or why and thus can’t control it. Starlink’s caps are nice in that if you exceed the cap you just get lowered in priority, not charged money or cut off. So maybe it’ll be self regulating.

My real fear is that instead of improving service the result of all this is Starlink is just going to add even more customers to an already overloaded network.

Update April 2026: this post is outdated. Starlink never imposed the data cap. My speeds in Grass Valley, CA improved and I’ve regularly been enjoying 200Mbps the past couple of years. I still see some evening congestion and some areas see worse performance.

Liftmaster 87504-267

This is gonna sound silly but one of the nicest home improvements we've done recently is install a new garage door opener, the Liftmaster 87504-267. It works so much better than my old insecure garage door!

Internet access is the surprise best feature; I use it all the time. Mostly to walk in and out of the garage door without my car. There's also a keypad remote I can mount outside so someone can punch in a code to open the door. Setting this all up was easy and reliable. There's even a way to give Amazon access to open your garage for deliveries.

The opener also has a camera. I would have skipped that if I'd known, saved some money. But it's actually quite useful! If I get a notification the garage door opens I can easily see on my phone what's going on. Basic live views seem to be free, there's a subscription if you want stored video.

Ken's favorite feature is the motion sensor that turns the light on. The lights on the unit are bright, it's enough to light the whole garage without having to flip a switch. I also appreciate there's a battery backup built-in so if the power goes out I can still easily open the door. The drive itself is smooth and quiet too, belt drives are a real improvement.

The #1 upgrade you should do for an older house is a dishwasher; they got a lot better about 15 years ago. But #2 may well be the garage door opener.

Relaxation Dynamics of a Lattice Spin System

Way back in 1994 I wrote an undergraduate thesis for my math degree at Reed College. It was a fun project, studying a discrete dynamic system that was an extension of the Ising model. Sort of cellular automata meets statistical mechanics. It’s the only significant thing I’ve written that’s not online (too lazy). Update July 2022: PDF is here.
A few years ago my colleagues from the Santa Fe Institute wrote a preprint from that work, Vortex Dynamics and Entropic Coulomb Forces in Ising and Potts Antiferromagnets and Ice Models. They were kind enough to list me as an author even though I barely understand half the paper! I do have the pretty pictures, though, plus a healthy appreciation of the complexity of discrete systems.
I’ve never met one of the co-authors, Cosma Shalizi. But thanks to his having a weblog I now know more about him than the other guys.

Starlink congestion

Starlink is oversold in North America. I've had the service since March 2021 and it's mostly great. But every evening it slows down. On bad nights I can't watch a single 1080p video stream reliably. Over half of Starlink customers report problems. Starlink's speed test app now admits "the network may be affected by slower speeds during busy hours". As if that were OK.

Overselling capacity is a common problem with American ISPs. More customers means more revenue and if customers get a crappy experience? Too bad, there's no regulation to stop them. Starlink has a serious financial challenge so of course they have an incentive to oversell. And service quality is likely to keep getting worse. Their user growth is accelerating and the new RV service means literally anyone can buy a dish now without waiting (albeit at a lower service tier.) They are adding capacity but their growth plan hinges on the troubled Starship launch vehicle.

Customers were promised better. Starlink was advertised as offering 100-200Mbps and 20ms latency; their legalese description promises 50-250Mbps / 20-40ms. My reality is speeds drop to 10-20Mbps every evening. Upload speeds are tiny, often well below 5Mbps. 20ms latency is a fantasy; 50ms is typical. And capacity is highly variable minute by minute, a technical challenge for rate limiting protocols.

The US government is giving Starlink $900M to sell rural Americans 100Mbps download / 20Mbps upload. But Starlink is delivering just a tenth of that download speed during peak hours and nowhere near that upload speed ever. I hope the FCC RDOF contract includes measured performance targets.

I am still grateful for Starlink, it's significantly better than anything else I can get in Grass Valley, CA. But they're making a business decision that's bad for customers. It's a reminder of how important it is to have Internet competition. Investing in wired infrastructure is as important as ever.

Back to Goodreads

I’m back to using Goodreads but I lost my friends list, if you use Goodreads please add me as a friend.

After Goodreads lost my account I was furious and of course intended to never use it again. But to their credit, Goodreads did some extra work and managed to get me a copy of all my lost review data that I could import. And in the meantime I’d come to really miss Goodreads and decided I’d prefer to go back to using it.

After my experience I got interested in the IndieWeb idea of POSSE, Publish on your Own Site. You publish content like short updates or book reviews on your own infrastructure, then syndicate it to Twitter or Goodreads as appropriate. I like the spirit of owning your own data. But it requires you have your own infrastructure to publish to. I set up a basic Hugo blog for book reviews but it just doesn’t cut it. Goodreads offers so much more. Reviews are published in the context of a database of books, quickly crosslinked by author and genre and with publishing data and covers. Also Goodreads is social, reviews are shared with friends. That second part is why I didn’t switch to The StoryGraph; it’s a promising product but the community is small.

Still I’ve learned a hard lesson; your data isn’t safe on any cloud service. Making backups of your data is a good idea, I now have data dumps from 15 services. Although you still need a product to make that data useful. I’m still curious how Goodreads lost my data, they haven’t told me. One thing this whole debacle got me thinking is how dangerous account deletion is.

Delays when deleting data

Consumer websites need to be very careful about data deletion. There's a risk of an account being hacked and deleted without the owner's consent.

The GDPR includes a right to erasure, California's CCPA has a right to delete. These are good laws, they allow an individual to require a company delete all personal data they have on someone. However this right also contains a risk. What if someone unauthorized requests the deletion? Proper deletion cannot be undone, in theory even backups should be deleted.

One solution is to delay the deletion and make every effort to contact the user before it's done. Some users might interpret the delay as the company acting poorly but I think it's an important protection against accidental or malicious deletion. Facebook has had a reasonable system for this for many years now; when you delete an account you have 30 days to change your mind. As a side effect some Facebook users keep their accounts in a perpetual state of almost-deletion, the super-logoff. Even better if the user's data is hidden while in the delete-pending state.

I don't know the legal niceties of whether a company can inject a delay. The GDPR language talks about "without undue delay", which seems to leave room for a safety net. CCPA is explicit about businesses having 45 or 90 days to "respond to a request to delete".

This whole post is motivated by my Goodreads disaster. One explanation for what happened is someone could have hijacked my Goodreads account and then deleted it to hide their tracks. At first I was outraged my data could ever be deleted. But Goodreads would be correct to do that in response to a valid request for deletion. And it looks like Goodreads will delete irrevocably immediately. (I'm not certain.) If they'd put in a 30 day delay I would have noticed in time. Speculating about this scenario made me realize that instantaneous deletion is a dangerous feature for any product.

Cloud service data dumps

After my Goodreads disaster I went and got dumps from every cloud service I care about that I could think to try. 13 in total, Twitter and Facebook and others. I'm impressed with the results.

The best of the data exports comes from Google Takeout. They were a pioneer in making a proper product out of data export and the Google Data Liberation Front did a lot of activism both within Google and externally to sell the idea. It's not an obvious thing for a company to do; letting customers download all their data opens the door to competitors. But it's the decent and right thing to do and it allows your power users to do complex things without much support.

Data export is also increasingly the legally required thing to do. The GDPR enshrines a right to data portability in the law governing businesses in the EU. California's CCPA also has a data access right. It's a little weaker than GDPR's but a lot of sites seem to just provide GDPR to everyone, or at least to Californians. These are excellent regulations; they protect consumers and enable competition. They do put a regulatory burden on the companies implementing them but it's not too huge and the technical infrastructure has other uses too. (Imagine, Goodreads could have backups of user data!)

One thing I hadn't appreciated is how hard it is to build something to use the data. Recreating a product like Goodreads or Gmail is a lot of work! In practice the exports seem most useful when some other commercial service is designed to import them. There's not a big ecosystem of open source tools to work with export data. Some of the data exports I got are pretty rough, low level dumps in CSV or JSON format. Then again Twitter has a whole working live webapp, you can browse and search nicely formatted tweets right from the files.

My Google data is the most valuable to me; I wrote up notes on what I found in my 67GB export. It's impressive; Takeout covers some 50+ Google products, many of which have done a thoughtful job making their exports another designed product feature. Not only did the Data Liberation Front get the company to export the data but they created an infrastructure and culture of supporting and improving those exports. It's a good thing.

Goodreads lost all of my reviews

Goodreads lost my entire account last week. Nine years as a user, some 600 books and 250 carefully written reviews all deleted and unrecoverable. Their support has not been helpful. In 35 years of being online I've never encountered a company with such callous disregard for their users' data. Update: Goodreads gave me a recovered copy of my data

Do you use Goodreads? Don't trust them with your data. Protect yourself with a backup; use their data export service right now. Consider quitting Goodreads entirely. LibraryThing and The StoryGraph are promising competitors. This blog post also has some ideas on DIY indieweb alternatives.

Don't trust any cloud service with the only copy of your data. Most companies are not quite so reckless but consider what you'd miss if an uncaring company lost your data. Many of the better services have data export products; Google Takeout is fantastic, Twitter has good export, as does Facebook and Instagram and Letterboxd and others.

I've enjoyed using a product like Goodreads. My plan now is to host my own blog-like collection of all my reading notes like Tom does. It will be a lot of work to set up. Fortunately not all is lost, I happened to take a data export last July and I can recover some of the more recent data from emails they sent to my friends. It's a shame they block Archive.org.

For anyone wondering how Goodreads could have simply lost all my data, I'm wondering too! It bespeaks contempt for users. And terrible system design, services should not be able to lose data irrecoverably. The specific bug is related to my removing Twitter API access to Goodreads last week (they stopped supporting Twitter login months before). Somehow that triggered their system to delete everything. Goodreads promises me it was a true delete, the data is wiped from their database. I don't believe this: sites generally flag data as deleted, they don't actually remove it. Goodreads also ignored my request to restore my data from backup. Either they don't have backups or they can't be bothered.

I've learned a hard lesson in trusting cloud services. Unfortunately just having a copy of your data isn't enough; it's a lot of work to build a useful product. In the meantime I will be more careful about which companies I trust. Goodreads has been in decline ever since Amazon bought them in 2013. Apparently an anti-competitive purchase, not a strategic acquisition.

Electrify

The best thing an individual American can do right now to fight global warming personally is to switch to electricity for all your energy needs. Your next car should be electric and your next home heater and water heater should be heat pumps. Rooftop solar is an excellent idea too.

That’s the central argument in Electrify, Saul Griffith’s new book about global warming (Amazon). He’s been talking about this for awhile; Electrify covers a lot of the same ground as his free self published Rewiring America and his Make articles.

The most interesting part of the new book isn’t the personal advice but rather his global plan for how the whole world mitigates global warming. He starts by pointing out how urgent the problem is: we have to start doing more right now, this very year, and there’s no time to wait on new technologies. Electricity is the best form of energy for transportation and storage. The basic idea is to shift from fossil fuel to electric consumption while in parallel adding more carbon-neutral electricity sources to the grid. He argues we’ll need 4x as much electricity in the US to achieve full electrification but this is a huge net gain (50%ish) in both total energy consumption and actual costs. He advocates for an effort akin to World War II mobilization to get it done, financed with low interest debt.

What I like best about his argument is it breaks the Gordian knot about “what can we do”? Electrify now and work on adding clean energy sources. I also like his holistic clarity, he really looks at whole-world energy consumption and economics. The optimism is great too. I find the argument convincing.

That being said, I also think global warming is a terrible problem that world politics won’t solve in time. We’re at 1.2C warming now. The Paris goal of 1.5–2C seems impossible. 3C seems inevitable and I suspect we’ll get to 4C at least before warming starts to reverse. That’s an enormous global catastrophe so big I think we have to consider geoengineering in parallel to decarbonizing to stave off the worst effects. As the book points out there’s a risk people will see geoengineering as an alternative to decarbonization. It’s not, but it might be a band-aid to give us time to get CO2 under control.